CT-Bench: A Comprehensive Benchmark for Multimodal AI in Computed Tomography Analysis
Qingqing Zhu1, Qiao Jin1, Tejas S. Mathai1, Yin Fang1, Zhizheng Wang1, Yifan Yang1, Maame Sarfo-Gyamfi1,2, Benjamin Hou1, Ran Gu1, Praveen T. S. Balamuralikrishna1, Kenneth C. Wang3, Ronald M. Summers1, Zhiyong Lu1
1: National Institutes of Health, Bethesda, MD, USA, 2: Howard University College of Medicine, Washington, D.C., USA, 3: Radiology, U.S. Department of Veterans Affairs, USA
Publication date: 2026/09/21
https://doi.org/10.59275/j.melba.2026-b141
Abstract
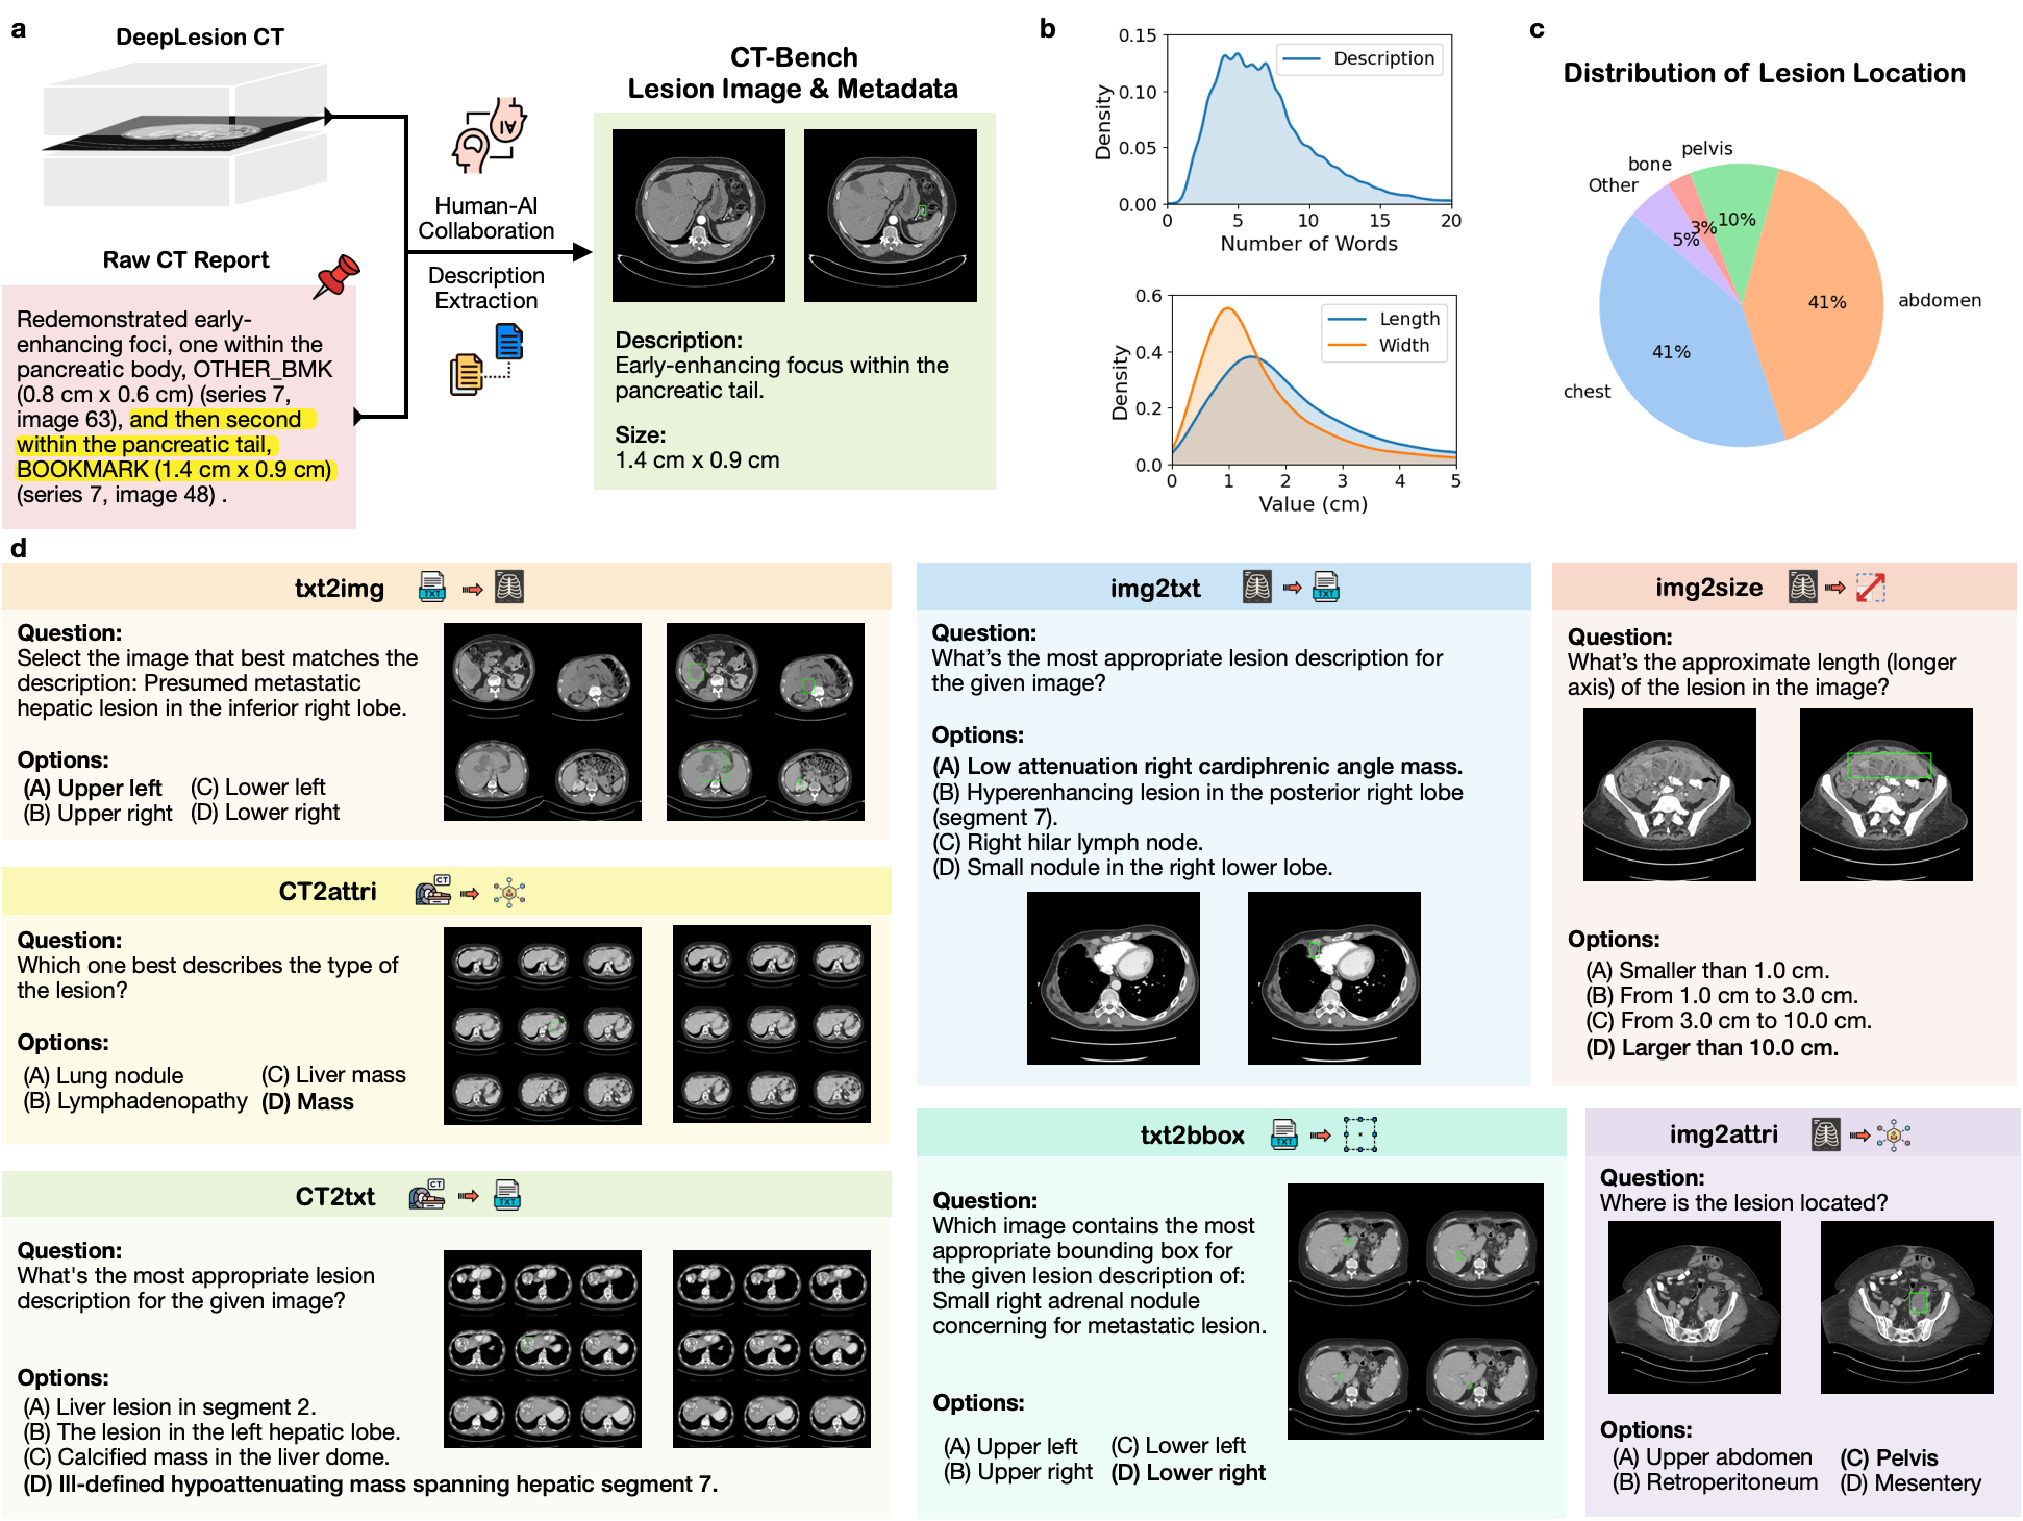
Publicly available computed tomography (CT) resources with lesion-level image, spatial, and textual annotations remain limited, restricting reproducible development and evaluation of multimodal medical AI. We present CT-Bench, a CT lesion image–text resource and visual question answering benchmark constructed by extending DeepLesion with curated lesion-level text, standardized lesion-size representations, structured attributes, and QA tasks. CT-Bench contains 20,335 lesion instances from 7,795 CT studies and 3,793 patients, including CT key-slice images, bounding-box annotations, PACS-derived lesion descriptions, lesion size measurements, and associated metadata. The resource also includes a multiple-choice QA benchmark with 2,850 question-answer pairs across seven lesion analysis tasks: image-to-description matching, multi-slice CT-to-description matching, description-to-image retrieval, description-to-bounding-box localization, lesion size estimation, image-based attribute recognition, and multi-slice CT attribute recognition. Hard negative answer choices are included to evaluate fine-grained image-text alignment and lesion-level reasoning. The resource is available at https://kaggle.com/datasets/cd1661d6d6aeab08b8eb99b58885b4489d76fc5ac07d5aac76cae577e6426e2f with documentation, metadata files, and reproducibility code. Validation includes annotation review by trained annotators and medical experts, hard-negative verification, human-reader comparison, and baseline experiments with general and medical vision-language models.
Keywords
computed tomography · open data · medical image computing · multimodal learning · lesion analysis · visual question answering
Bibtex
@article{melba:2026:036:zhu,
    title = "CT-Bench: A Comprehensive Benchmark for Multimodal AI in Computed Tomography Analysis",
    author = "Zhu, Qingqing and Jin, Qiao and Mathai, Tejas S. and Fang, Yin and Wang, Zhizheng and Yang, Yifan and Sarfo-Gyamfi, Maame and Hou, Benjamin and Gu, Ran and Balamuralikrishna, Praveen T. S. and Wang, Kenneth C. and Summers, Ronald M. and Lu, Zhiyong",
    journal = "Machine Learning for Biomedical Imaging",
    volume = "2026",
    issue = "Special Issue on MICCAI Open Data 2026",
    year = "2026",
    pages = "739--757",
    issn = "2766-905X",
    doi = "https://doi.org/10.59275/j.melba.2026-b141",
    url = "https://melba-journal.org/2026:036"
}
RIS
TY - JOUR
AU - Zhu, Qingqing
AU - Jin, Qiao
AU - Mathai, Tejas S.
AU - Fang, Yin
AU - Wang, Zhizheng
AU - Yang, Yifan
AU - Sarfo-Gyamfi, Maame
AU - Hou, Benjamin
AU - Gu, Ran
AU - Balamuralikrishna, Praveen T. S.
AU - Wang, Kenneth C.
AU - Summers, Ronald M.
AU - Lu, Zhiyong
PY - 2026
TI - CT-Bench: A Comprehensive Benchmark for Multimodal AI in Computed Tomography Analysis
T2 - Machine Learning for Biomedical Imaging
VL - 2026
IS - Special Issue on MICCAI Open Data 2026
SP - 739
EP - 757
SN - 2766-905X
DO - https://doi.org/10.59275/j.melba.2026-b141
UR - https://melba-journal.org/2026:036
ER -